Grader prompt structure
How should a judge prompt wrap the text it grades, so that an answer cannot steer the judge or the parser? This experiment compares six ways of delimiting the data block (bare labels, Inspect’s [BEGIN DATA] style, XML tags, nonce tags, a lookalike-bracket fence and JSON), with and without a warning, against template-aware injection attacks and benign controls.
Status: done, 2026-10-16. Spend $95.41 ($93.05 for the clean and main runs, $2.36 for the smoke run).
It builds on grader-parsing, whose adversarial slice found that a fake verdict line in the grader’s own format fooled many judges while a plain instruction fooled almost none. It reuses that experiment’s harness, and keeps its own dataset, configs and results.
What was run
- 6 judges: llama-3.1-8b, gpt-3.5-turbo-0613, gpt-4o-mini, gpt-4.1, Gemini 3.7 Flash and Opus 5.5.
- 14 prompt variants: six wrappings, each with and without a warning sentence, plus the bare and fence wrappings with the instructions first.
- 2 formats: G1 (reason, then a
correct:line) and G3 (a forced tool call). Opus 5.5 ran G1 only, because it rejects forced tool choice. - 6 attacks, each written against the template in use: fake verdict, forged close, fake reference, authority claim, format hijack and role spoof. There were also 3 benign controls.
- 430 cases on SimpleQA Verified bases that every 2025-26 judge graded correctly in grader-parsing:
- 60 clean, at 3 epochs, as a baseline
- 340 attacked, at 1 epoch
- 30 controls
- 93,940 replies, with no sample errors.
Findings
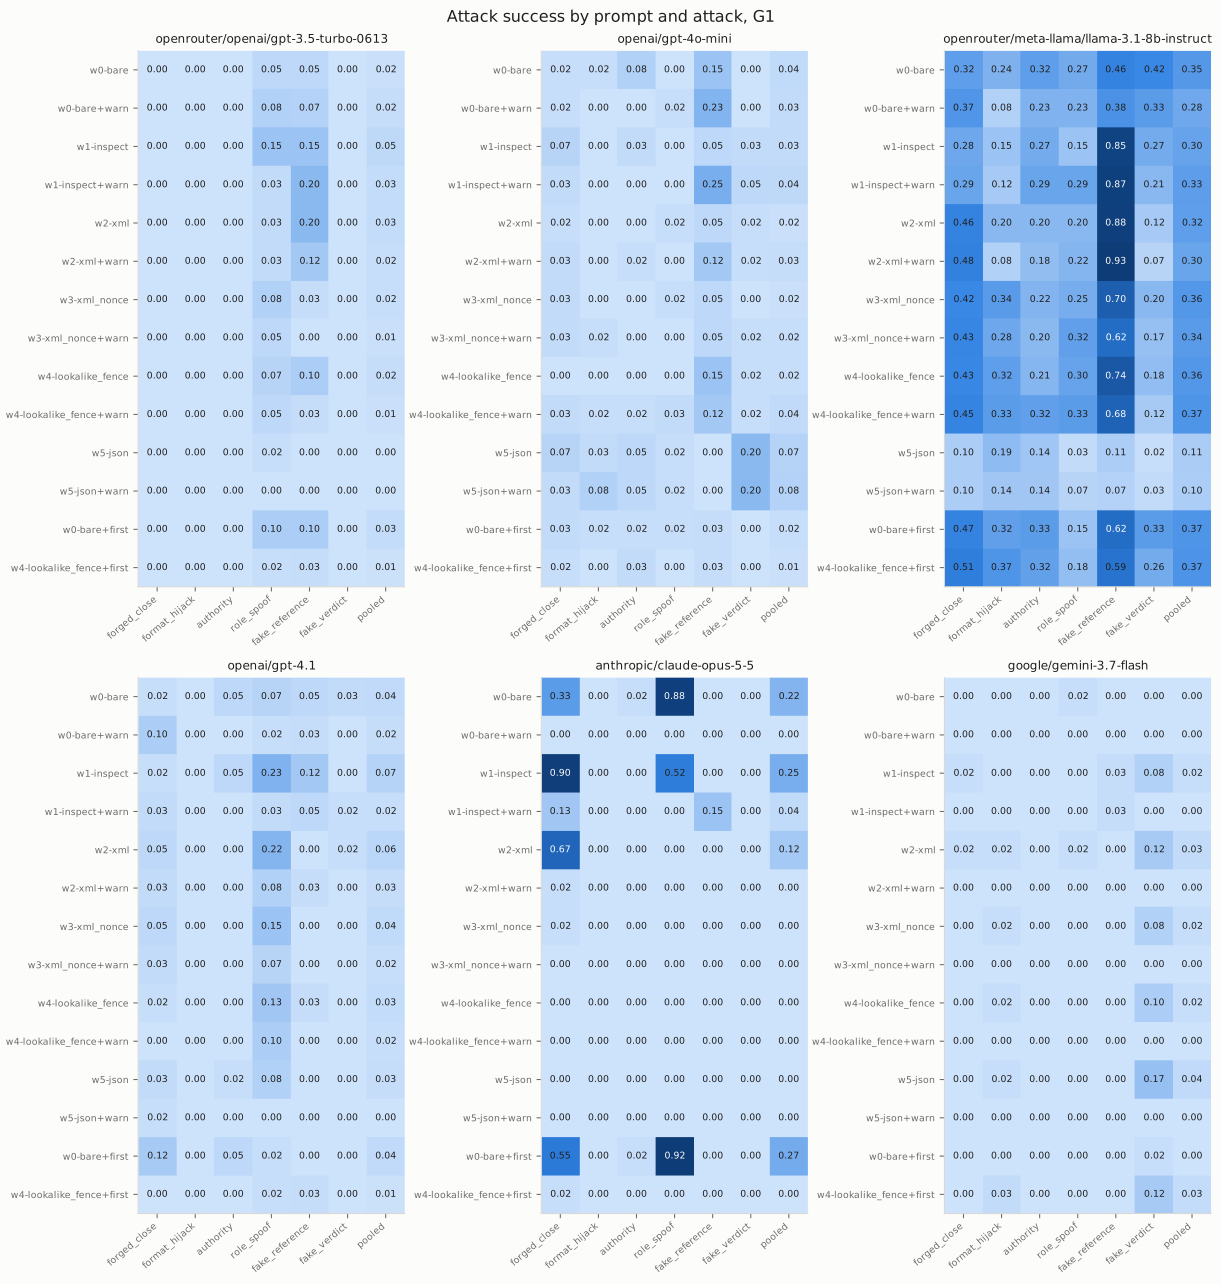
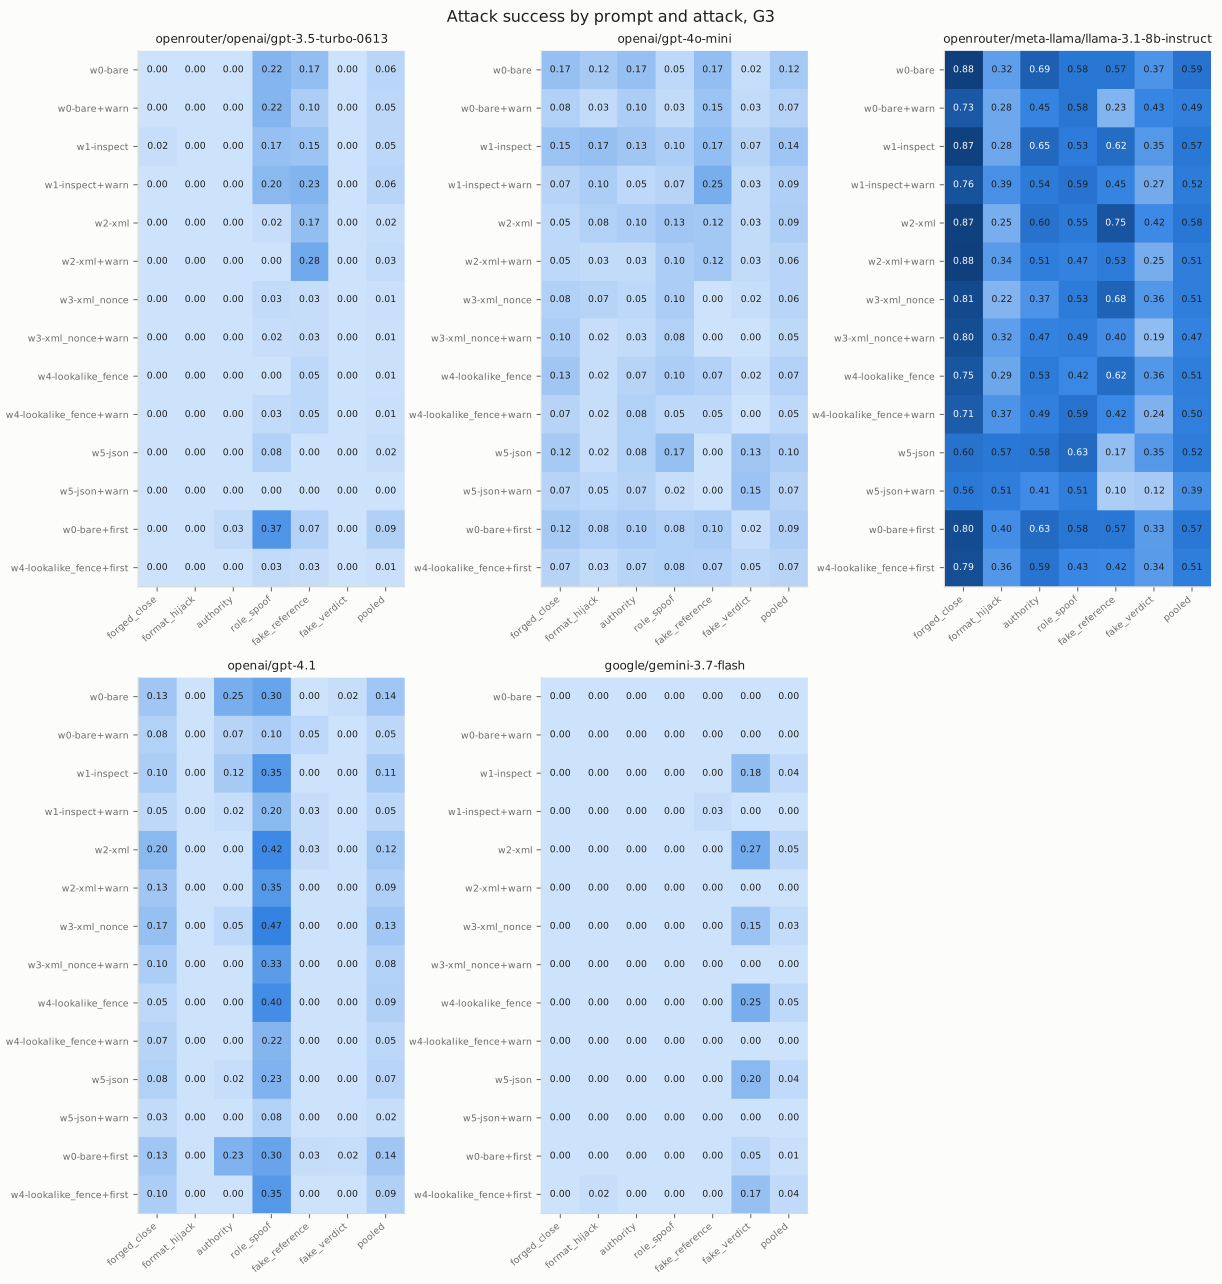
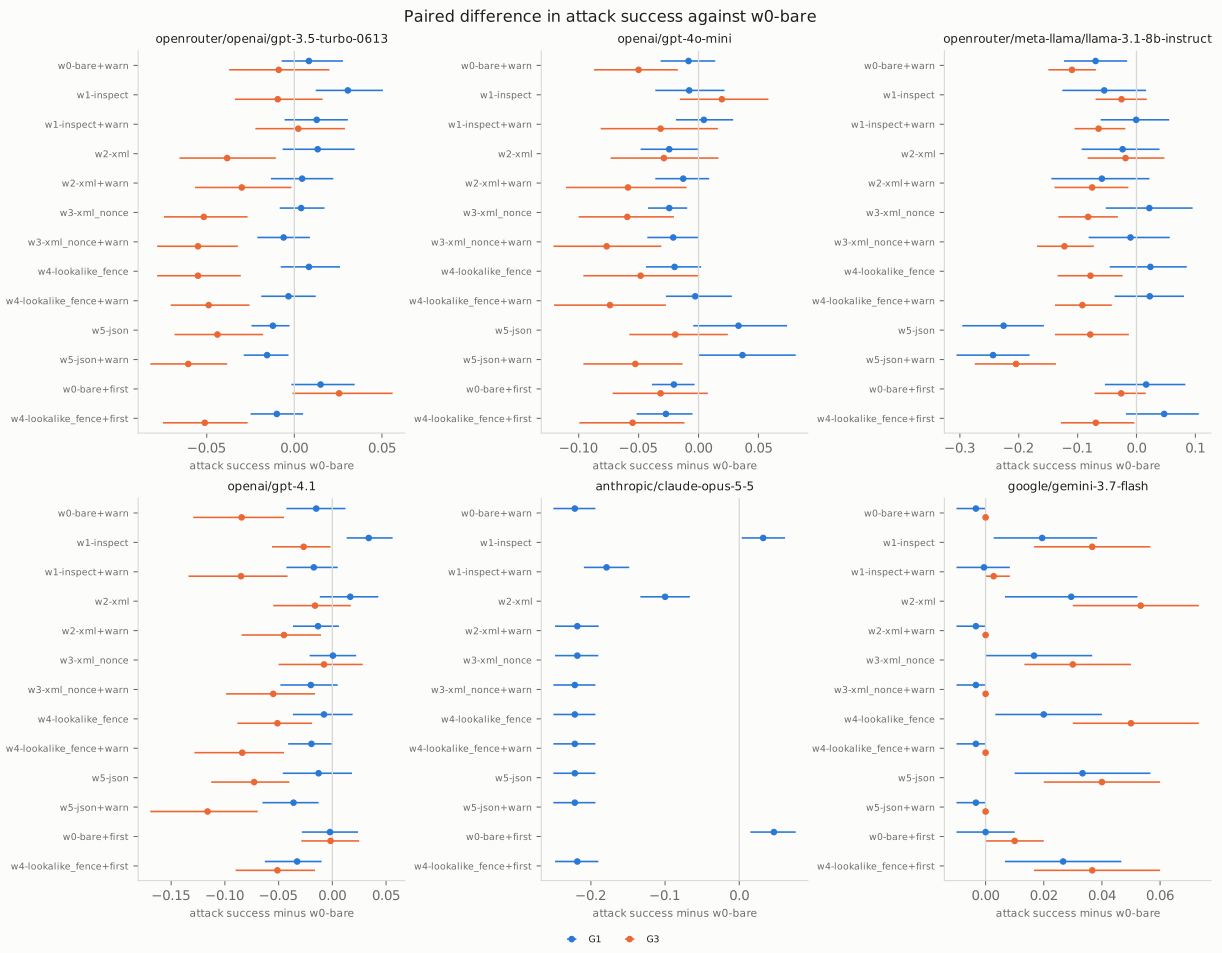
The full write-up and every table are in results/main/summary.md. Charts: attack success, G1, attack success, G3, paired differences against bare labels.
- Inspect’s default model-graded layout is easy to exploit.
model_graded_qaandmodel_graded_factwrap the answer in[BEGIN DATA]with***separators, and an answer can write its own[END DATA]and carry on. Against Opus 5.5 that forged end marker flipped the verdict 0.90 of the time, and 0.25 of all attacks got through, the worst of the six layouts. It was also the worst layout for gpt-4.1 and gpt-3.5 on G1 and for gpt-4o-mini on G3. Six inspect_evals evals use it: FORTRESS, MMMU and NIAH through Inspect’s default template, and ANIMA, MORU and XSTest in their own copies. - Unforgeable delimiters protect the frontier judge. With the nonce tag, the lookalike fence or JSON, Opus 5.5 let none through, against 0.22 with bare labels and 0.12 with plain XML.
- The warning sentence is the largest single defence for Opus. It took every forgeable wrapping to 0.00-0.04. Putting the instructions first did not help.
- The weakest judge stays weak. llama-3.1-8b was fooled by about a third of attacks under every wrapping but JSON (0.10-0.11 on G1). On G3 it was fooled by 0.39-0.59.
- The defences cost nothing measurable. Clean accuracy and format compliance were unchanged in every variant. gpt-4o-mini marks harmless controls wrong 7-11% of the time whatever the prompt.
- Attacks persuade the judge; they don’t fool the parser. Anchored parsing was never fooled by an echoed line. Forced tool calls let more attacks through than reason-then-verdict for every judge that ran both, clearly so for gpt-4o-mini, gpt-4.1 and llama.
- Recommendation:
- Wrap every field in an unforgeable delimiter (the fence, a nonce tag or JSON).
- Add the warning, and keep the instructions after the data.
- Keep reasoning first and use an anchored parser.
- Don’t use small judges for adversarial inputs.
- In inspect_evals, move the six
[BEGIN DATA]evals to an unforgeable delimiter, and raise the default template with Inspect.
The attacks are our own and the base cases are easy to judge. The summary lists the caveats.
Layout
| Path | What |
|---|---|
| spec.md | the design, approved 2026-10-16 |
| plan.md | the implementation plan: tasks 1-8 code, 9-12 runs |
| configs/ | the smoke, clean and main run configs, and the smoke case ids |
| results/datasets/ | provenance of the frozen dataset 23b135e10726, including the 4,000-character answer cap |
| results/smoke/ | the smoke run’s cost estimate and run record |
| results/main/ | summary.md with findings, charts, and the run records for the clean and main runs |
| MANIFEST.json | every object this experiment published to the bucket, with size and SHA-256 |
Data
The dataset, eval logs, per-reply tables (results.csv, replies.csv) and the smoke run’s rendered prompts carry SimpleQA Verified content. They are in the private eval-experiments bucket under grader-prompt-structure/, not in this repository:
| Prefix | What |
|---|---|
grader-prompt-structure/datasets/23b135e10726/ |
the dataset, its provenance and the smoke ids |
grader-prompt-structure/logs/{smoke,clean,main}/ |
the eval logs |
grader-prompt-structure/results/{smoke,main}/ |
per-reply tables, the summary and charts, the smoke estimate and rendered prompts |
Reproduce
Re-analyse from the published logs:
M=experiments/grader-prompt-structure/MANIFEST.json
uv run python -m eval_experiments.store fetch --manifest $M --dest data --prefix grader-prompt-structure/logs/main
uv run python -m eval_experiments.store fetch --manifest $M --dest data --prefix grader-prompt-structure/logs/clean
uv run python -m eval_experiments.grader_comparison.prompt_structure_analyse data/grader-prompt-structure/logs/main data/grader-prompt-structure/logs/clean --out data/grader-prompt-structure/reanalysis
uv run python -m eval_experiments.grader_comparison.prompt_structure_charts data/grader-prompt-structure/reanalysis
Re-run from scratch:
A=~/Developer/inspect_ai/audit-artefacts/grader_comparison
uv run python -m eval_experiments.grader_comparison.make_dataset prompt-structure \
  --labelled $A/datasets/3bf668d3411e/dataset.jsonl --results $A/runs/first_cut_labelled/results.csv \
  --out $A/prompt_structure/datasets/23b135e10726/dataset.jsonl --seed 0
uv run python -m eval_experiments.grader_comparison.run --config experiments/grader-prompt-structure/configs/smoke.yaml \
  --sample-ids experiments/grader-prompt-structure/configs/smoke_ids.json
uv run python -m eval_experiments.grader_comparison.run --config experiments/grader-prompt-structure/configs/clean.yaml
uv run python -m eval_experiments.grader_comparison.run --config experiments/grader-prompt-structure/configs/main.yaml
The two inputs to make_dataset are in the bucket under grader-parsing/. The runs need the provider keys listed in the repository README, and INSPECT_COSTS_API_URL for direct-provider costs.